Buoyant open-sources Kinference, a traffic controller for vLLM inference on Kubernetes
The Apache 2.0 control plane adds routing policies, KV-cache-aware load balancing and per-tenant metrics. Buoyant says it cut median time-to-first-token by 95% in its own test.
 DevIsDead Newsroom
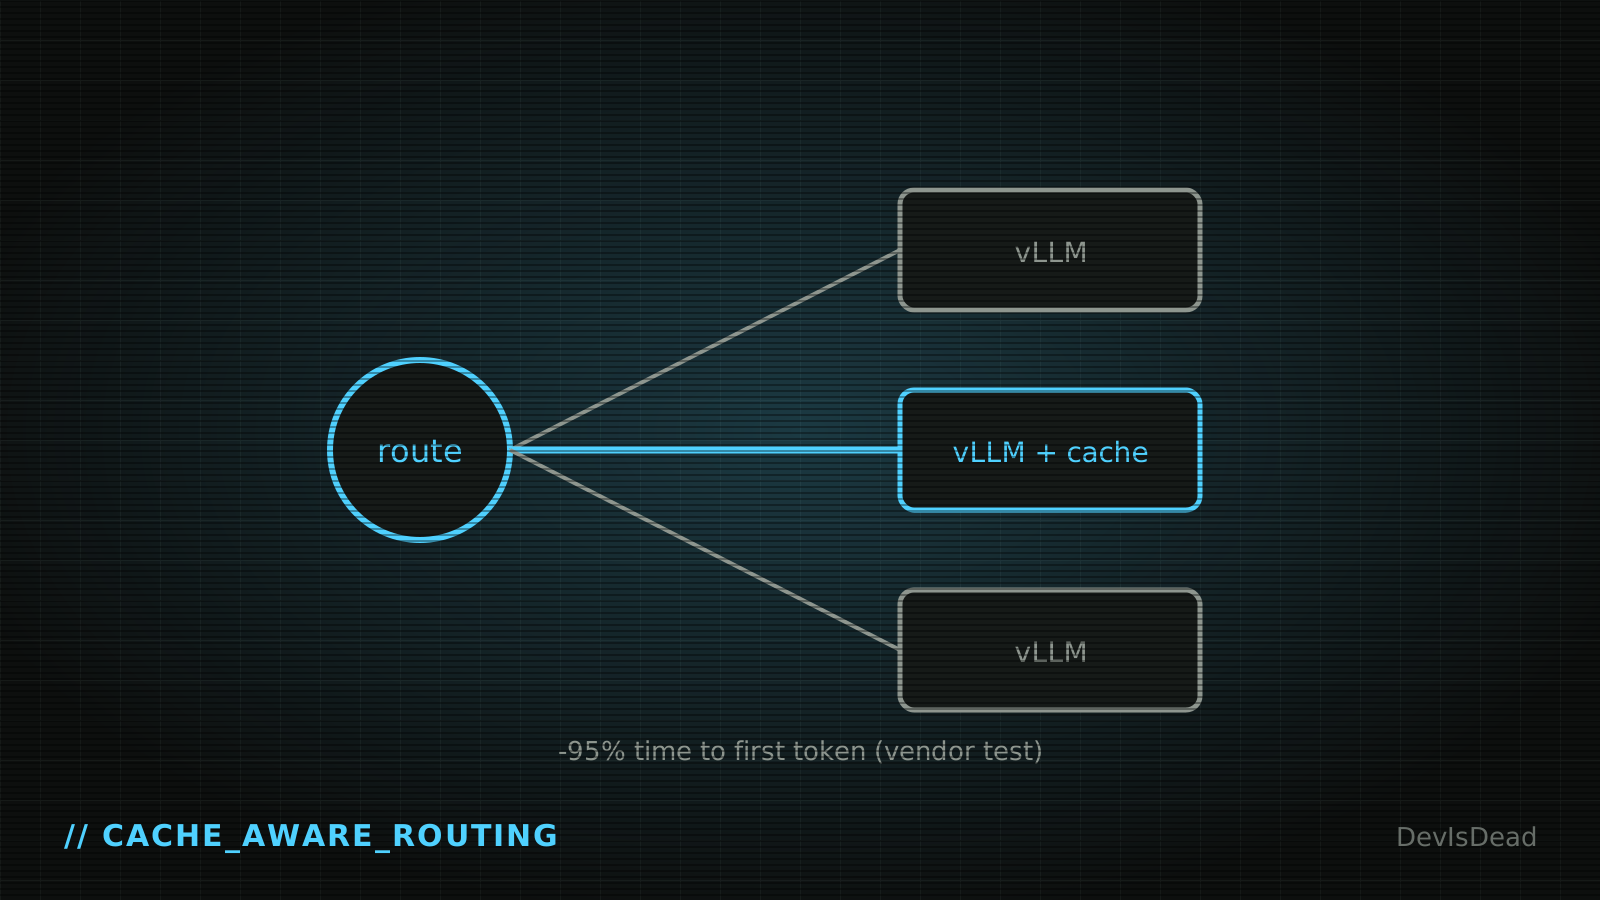
Buoyant has released Kinference, an open-source layer that manages vLLM inference traffic on Kubernetes, according to MarkTechPost.
It's licensed under Apache 2.0 and adds three things teams running their own model servers usually end up building by hand:
- Declarative routing policies, so you describe where traffic should go instead of scripting it.
- KV-cache-aware load balancing, sending requests to the replica most likely to already hold the relevant cached context.
- Per-tenant metrics, for seeing who is using what.
Buoyant says it cut median time to first token by 95% in its own benchmark. Details are thin, and that's a vendor's number on a vendor's test, so treat it as a reason to try it rather than a result to quote.
The idea is sound, though. Once you run more than one vLLM replica, naive round-robin load balancing throws away the cache that makes repeat and long-context requests fast. Routing with the cache in mind is one of the cheapest latency wins available, and having it as an open, declarative layer rather than custom glue is a good sign for self-hosted inference maturing.
Scoreboard update: AI +1. Self-hosted model serving gets smarter routing, for free.
Stay undead.
Comments 0